RAG and vector search rely on your own data, ensuring that answers originate from verified sources your team trusts.
When you pose a business question to a general-purpose model, it answers by filling gaps with plausible patterns. Retrieval-augmented generation stops this. We link your model to a vector database and perform vector search on embeddings of your documents, records, and systems. This guarantees that each answer is pulled from your actual data before the model generates a response.
This technology allows semantic search, internal knowledge assistants, and AI features that rely on your specific content rather than public internet data. It forms a central part of our process. Search and retrieval systems work effectively only when the underlying data is accurate, current, and organised for machine queries. We place this foundational data work as a priority from the start.
You may apply the same process to create support chatbots, document assistants, or internal search tools. You need to transform the content into embeddings and index it for fast retrieval. You then attach this data to the model so it uses the specific facts prior to generating a response.
Our RAG consulting covers the corpus audit, the retrieval design, the evaluation set, and the integration with your existing team tools. The guide to what RAG consulting involves describes each stage and lists the questions you should ask before you commit.
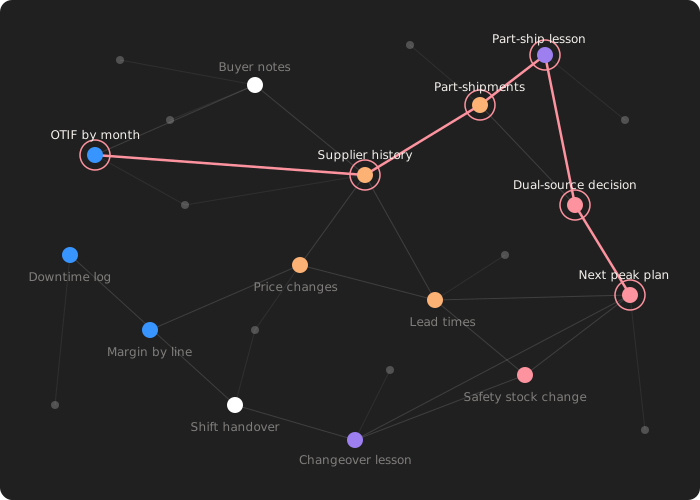
The system pulls each answer from your verified content and systems rather than relying on the model's general training.
Vector databases are built and optimised for rapid searches, even with large or complex datasets.
You may employ the same retrieval layer for search, chat, and summarisation. This lets you build the component once and reuse it for multiple functions.
We version and validate each record. Each record contains lineage data enabling you to audit it back to its original source.
Vector search finds information based on meaning rather than exact keyword matches. Your content is transformed into numerical embeddings and stored in a vector database. When a user submits a query, it is turned into an embedding using the same method to locate the most similar results. This process enables a RAG system to retrieve specific passages from large document collections within milliseconds.
A vector database holds content as embeddings. These mathematical representations let a model search for meaning rather than exact keyword matches. Retrieval-augmented generation happens when this search process supplies data to a language model. The model pulls the most relevant content and uses it to generate an answer. We have supplied more detailed explanations of these concepts: what a vector database is and how embeddings power AI search, and how RAG works for teams.
We pinpoint the specific documents, records, and systems your AI must access and those it should be barred from reaching.
Text, tables, and metadata are transformed into vector representations intended for retrieval rather than storage.
We choose and configure the database according to your performance, scale, and compliance requirements. We do not automatically select a particular vendor.
Your LLM or API pipeline is linked to the vector store. This enables the system to automatically fetch data prior to generating a response.
Observability, drift detection, and feedback loops keep the system accurate as your data and usage patterns change.
Vector search identifies information using meaning rather than exact keyword matches. Your content is transformed into numerical embeddings and stored in a vector database. When you submit a query, it undergoes the same conversion to locate the closest matches. This technology lets a RAG system retrieve the correct passage from thousands of documents within milliseconds.
RAG is short for retrieval-augmented generation. This process links a vector database to a language model. The model pulls relevant and verified content for its response instead of relying only on data from its original training.
This process gives the model factual data to check its responses. A model that retrieves your verified content before answering has fewer hallucinations than a model that depends solely on its internal memory.
We do not use that approach. We first design for your data, performance, and governance requirements. We then choose the vector store that satisfies those needs rather than defaulting to a particular vendor.
Yes. We add retrieval capabilities to your existing chatbots, internal tools, and API workflows rather than requiring you to build a new platform.
Each system employs automated evaluation, embedding validation, and observability dashboards. These tools let us monitor accuracy continuously rather than assuming it stays stable after launch.
RAG consulting includes the tasks needed to transition from a demonstration to a production retrieval system. We examine the documents and access permissions that the system uses. We create the chunking and embedding strategies. Our team assembles an evaluation set to confirm that the system retrieves the correct passages. We link the retrieval process to your model and tools. Finally, we provide a system that your staff can operate on their own.
Search and retrieval is usually the first capability you should build. This process confirms that your data foundation works before you add more complex features. Talk to us regarding the requirements your data must meet to support this function.
Tell us where your data is today and what you want AI to do. We'll come back with a straight answer on what your foundation needs and where the quickest real win is.
Talk to us